Built-in AI gateway
Understand, manage and optimise your LLM traffic.
Every model call your agents make goes through Distri’s gateway. It is traced end to end, attributed to the agent, the end user, the API key and the use case, held to your limits, and routed to whichever provider the agent uses. Nothing extra to deploy: it is part of every workspace.
What the gateway does
One place for every model call.
Embedded agents, bots, workflows and direct API calls all reach the model through the same gateway, so one dashboard shows all of it.
End-to-end observability
Follow every call from the agent to the model and back.
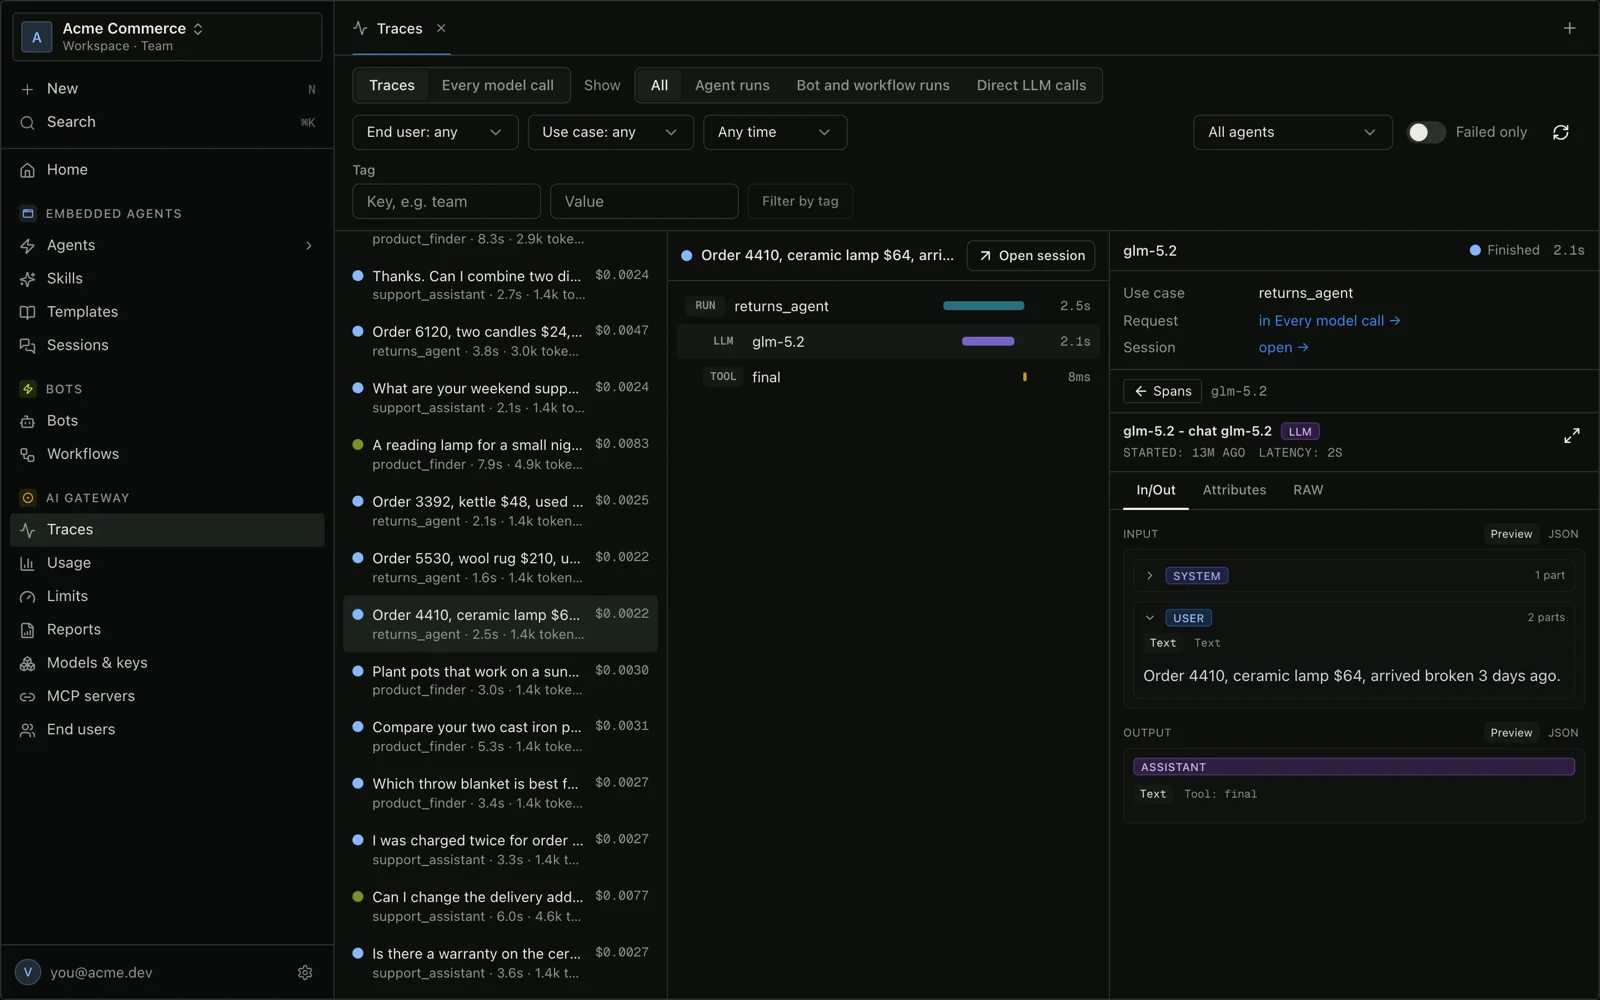
Every agent run, bot and workflow run, and direct model call is a trace: a tree of agent, model and tool spans with timings, tokens and cost. Filter by end user, use case, tag or agent, or show only the failures.
Usage attribution
Every call, split by who and what made it.
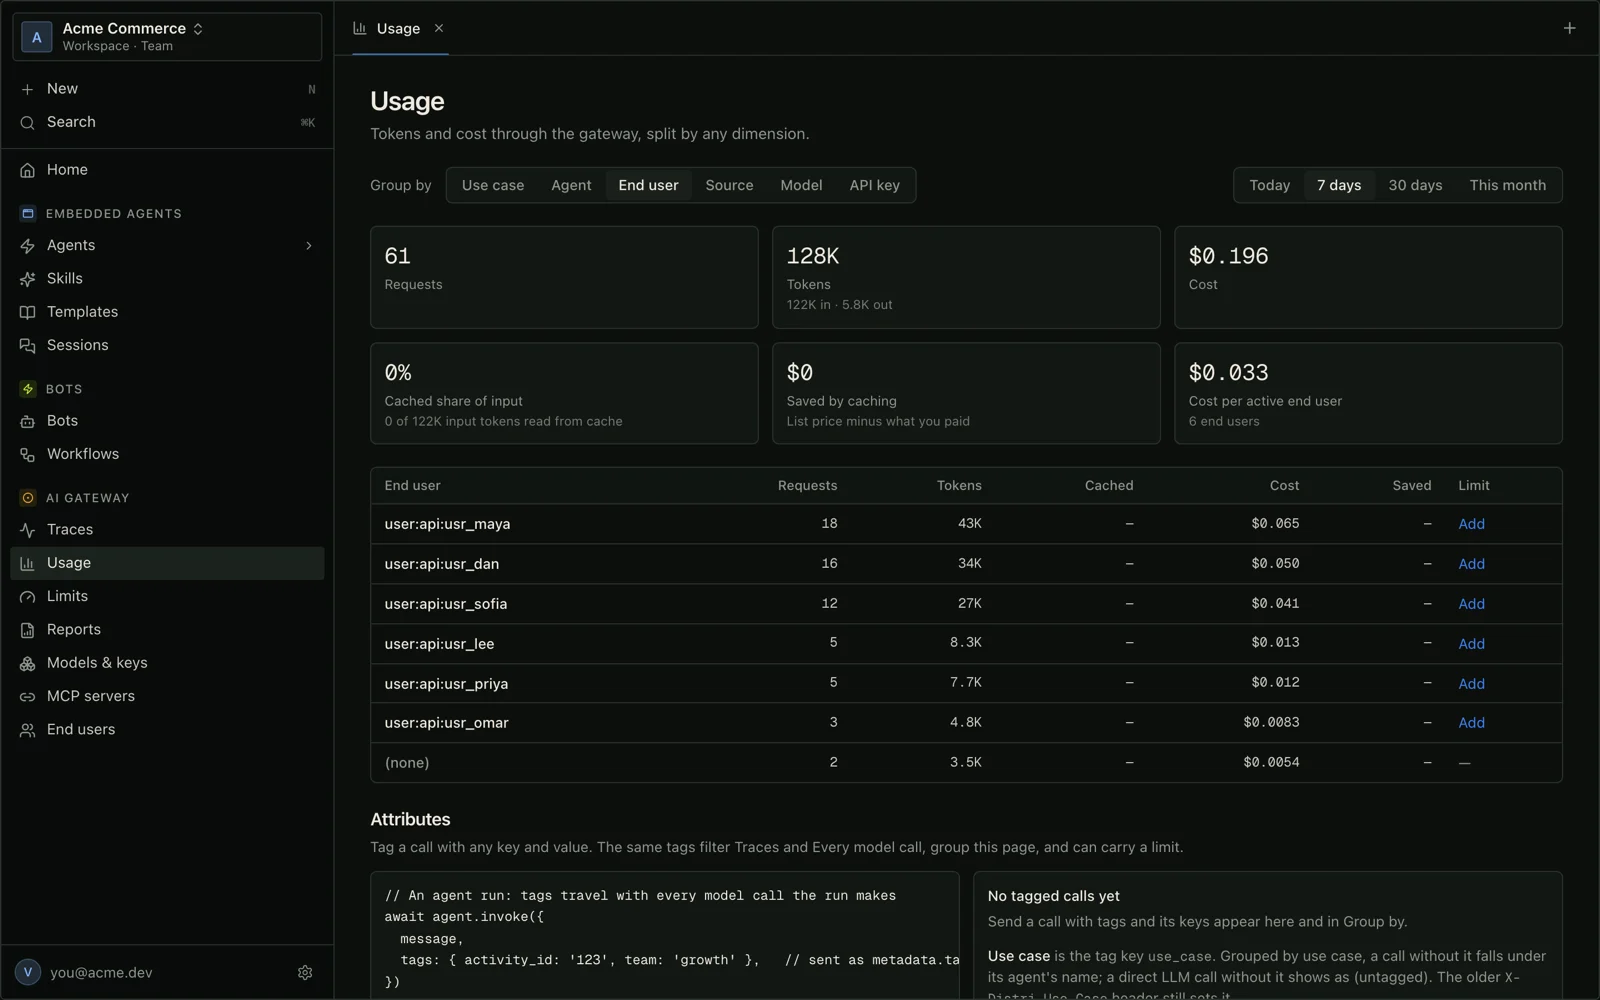
Group usage by any dimension, over today, 7 days, 30 days or this month. Costs use each provider’s list price; cached input and what caching saved are shown on their own. Tag a call with any key and value and the same tag groups this page, filters traces and can carry a limit.
- Use case
- Agent
- End user
- Source
- Model
- API key
End users
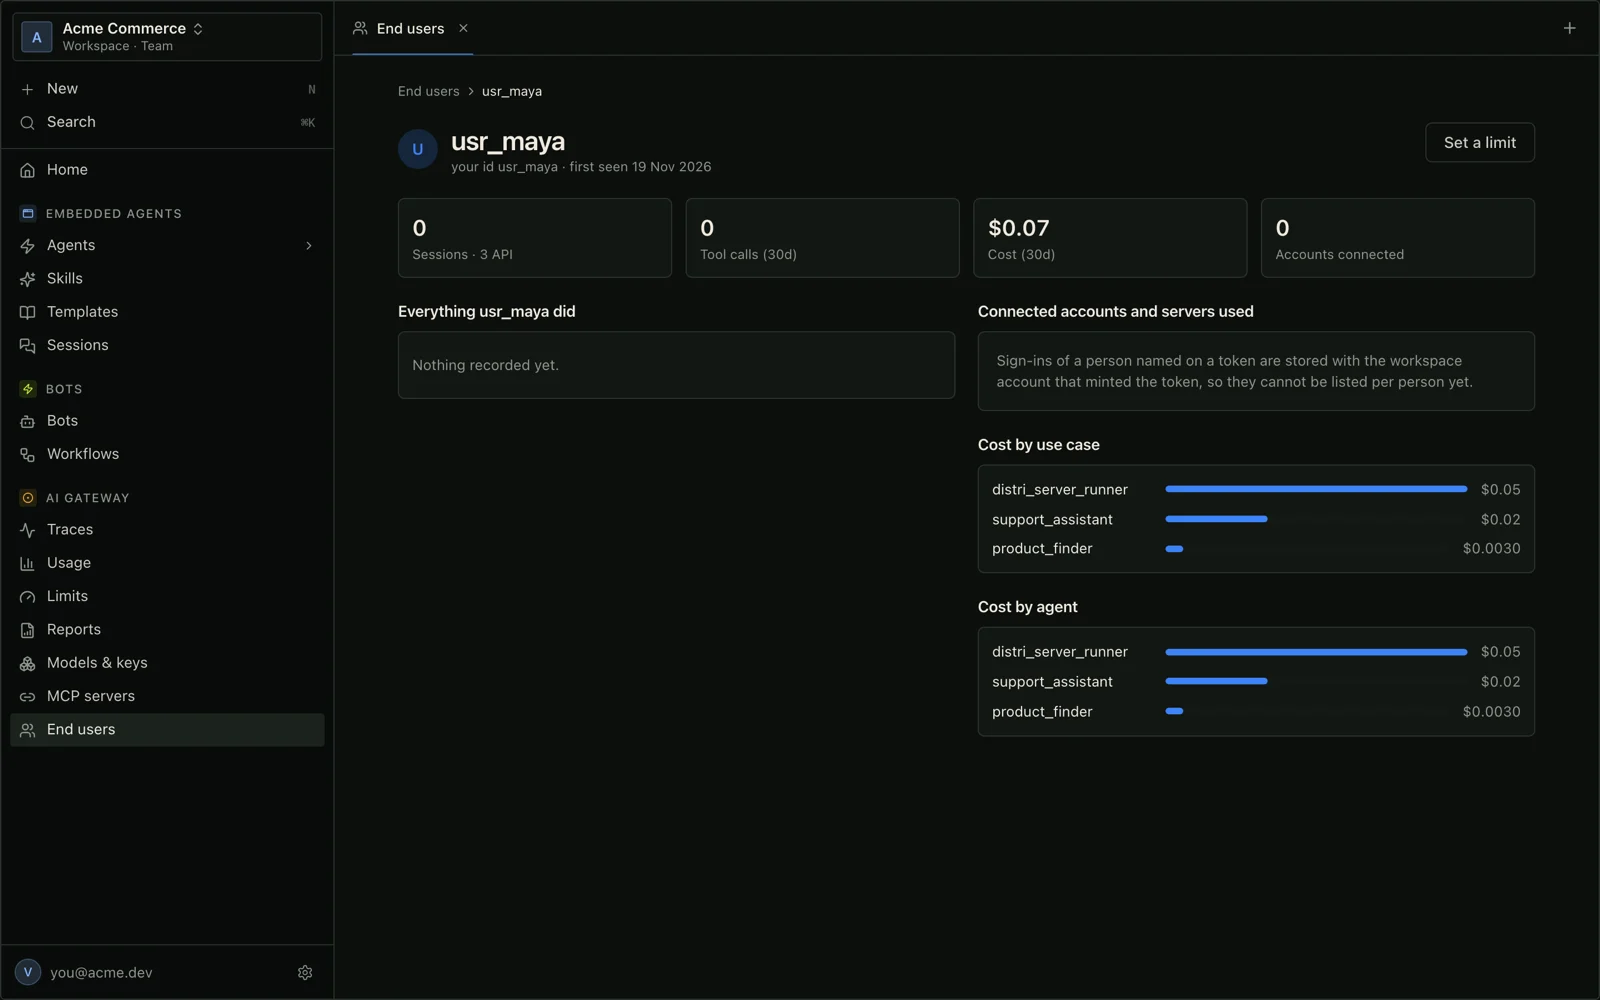
Name the person once. Every surface counts them.
Your server names the person, so they cannot spoof it: per call with a header, or on a short-lived token you give to their browser. People messaging a bot on Telegram, WhatsApp or Discord are identified automatically. Every agent is an A2A-compatible endpoint, so calls from your backend or from another agent are counted the same way.
# From your server: name the person on each callcurl https://api.distri.dev/v1/agents/support_assistant \  -H "Authorization: Bearer $DISTRI_API_KEY" \  -H "X-Distri-End-User: usr_8812" \  -d '{ "jsonrpc": "2.0", "id": "1", "method": "message/send", ... }'
# Or mint a token for the signed-in person and hand it# to the embed or @distri/react in their browsercurl https://api.distri.dev/v1/token \  -H "Authorization: Bearer $DISTRI_API_KEY" \  -d '{ "scope": "user", "identifier_id": "usr_8812" }'# → { "access_token": "…" }
Limits
Caps checked before every provider call.
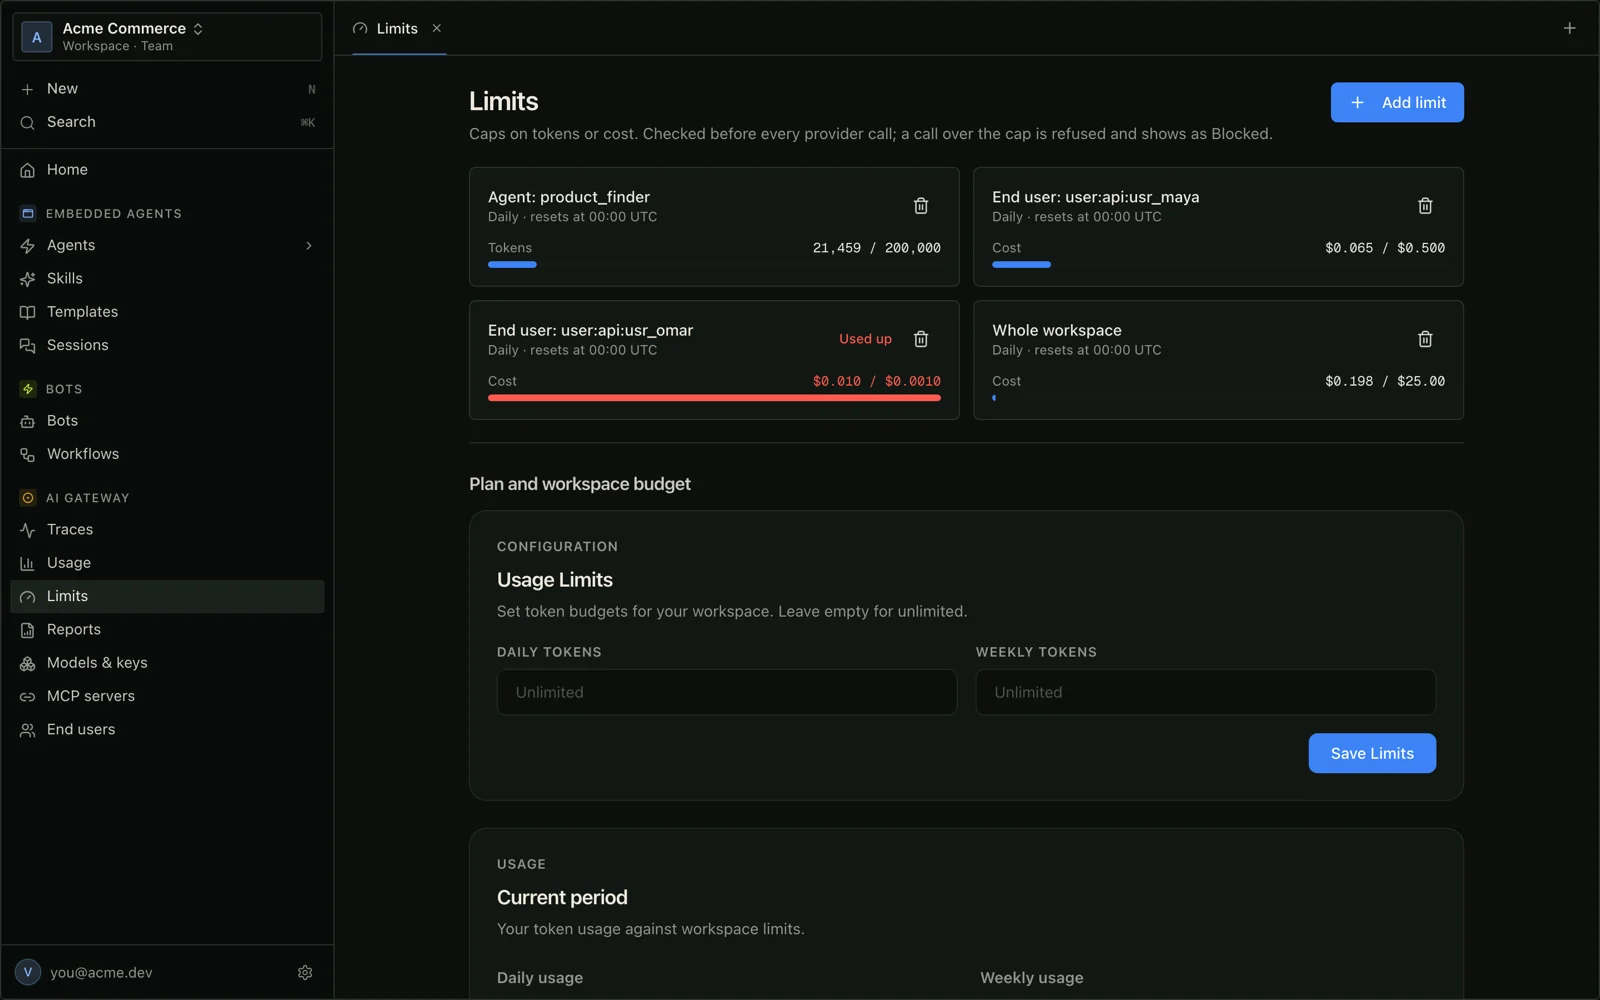
Cap tokens, cost in USD, or both, per day, per rolling week or per month. A call over the cap is refused before it reaches a model, answers 429 with when it resets, and shows as Blocked. The dashboard flags a limit that is used up.
A limit can apply to
- Workspace
- Agent
- Use case
- Tag
- End user
- API key
- Embed client
# Cap one end user at $0.50 a daycurl -X PUT https://api.distri.dev/v1/gateway/limits \  -H "Authorization: Bearer $DISTRI_API_KEY" \  -d '{ "scope": "end_user", "scope_value": "user:api:usr_8812",        "period": "day", "max_cost_usd": 0.5 }'
# The next call over the cap never reaches the model:HTTP/1.1 429 Too Many Requests{ "message": "End user user:api:usr_8812's daily limit  of $0.50 is used up. It resets at 00:00 UTC." }
Optimise
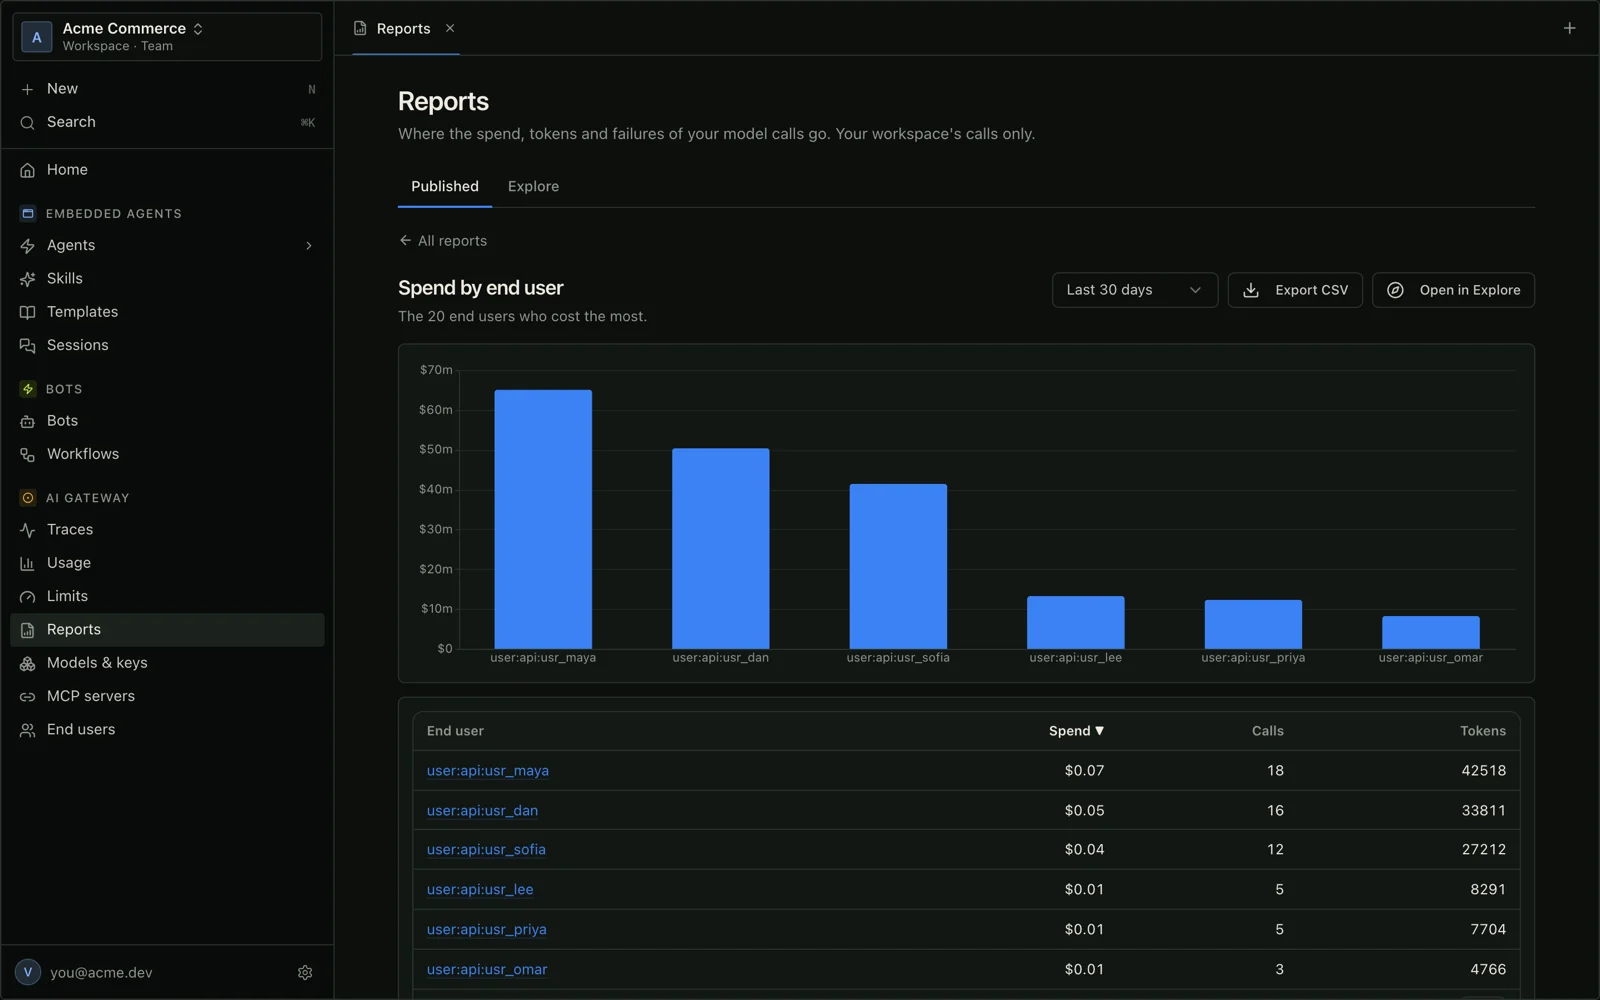
See where the spend, tokens and failures go.
Ready-made reports for the questions finance and engineering ask: which agents and end users cost the most, what caching saved, which models fail, and what fills the input. Each exports to CSV. Build your own view in Explore and save it for the workspace.
Multiple providers
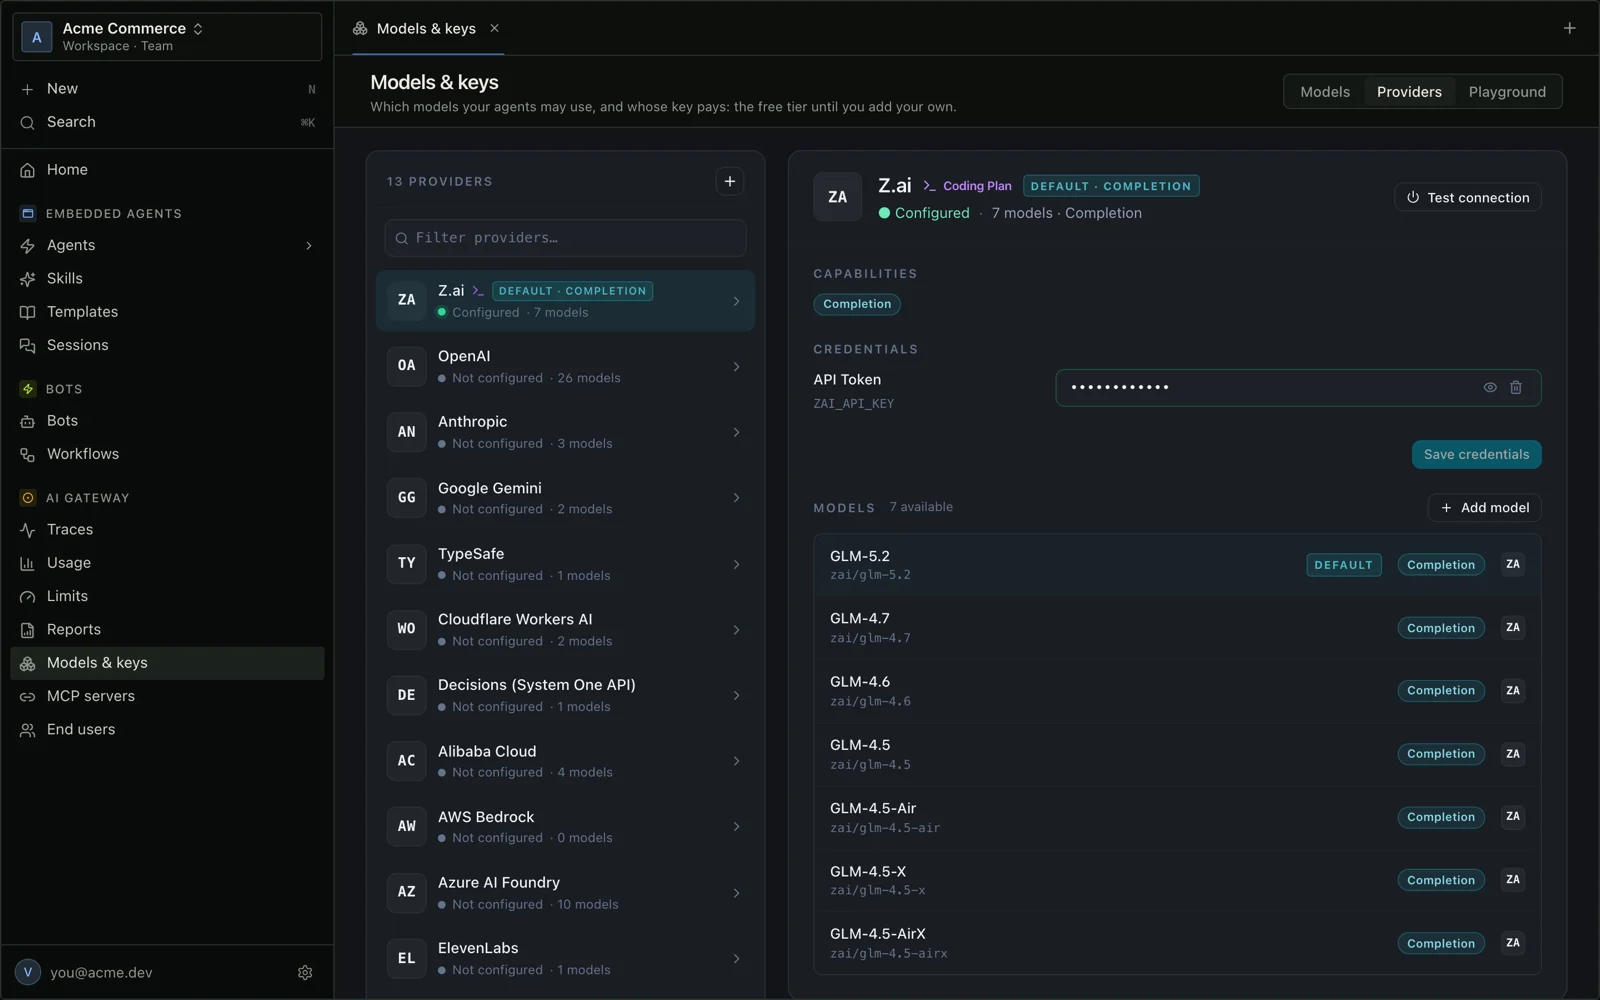
Any provider. Your keys. A model per agent.
Agents run on the free tier until you add your own key; then the provider account, its rates and its data terms stay yours. Pick a default model for the workspace and a different one for any agent. Test a connection and try models in the playground.
- OpenAI
- Anthropic
- Google Gemini
- Google Vertex AI
- Azure AI Foundry
- AWS Bedrock
- Alibaba Cloud
- Z.ai
- Cloudflare Workers AI
- fal.ai
- ElevenLabs
- OpenAI-compatible
Every model call, accounted for.
The AI gateway is built into every Distri workspace, free tier included.