Open Source Managed Agents for AI Native Apps
Embed deep agents directly in your products. Built in Rust.
Read distri.dev/SKILL.md to set up my agentimport { DistriProvider, Chat } from '@distri/react';
export function Assistant() { return ( <DistriProvider config={{ baseUrl: 'https://api.distri.dev/v1', clientId: 'dpc_…', workspaceId: '…', }}> <Chat agentId="shop_assistant" externalTools={[addToCart]} // your own function /> </DistriProvider> );}See it work
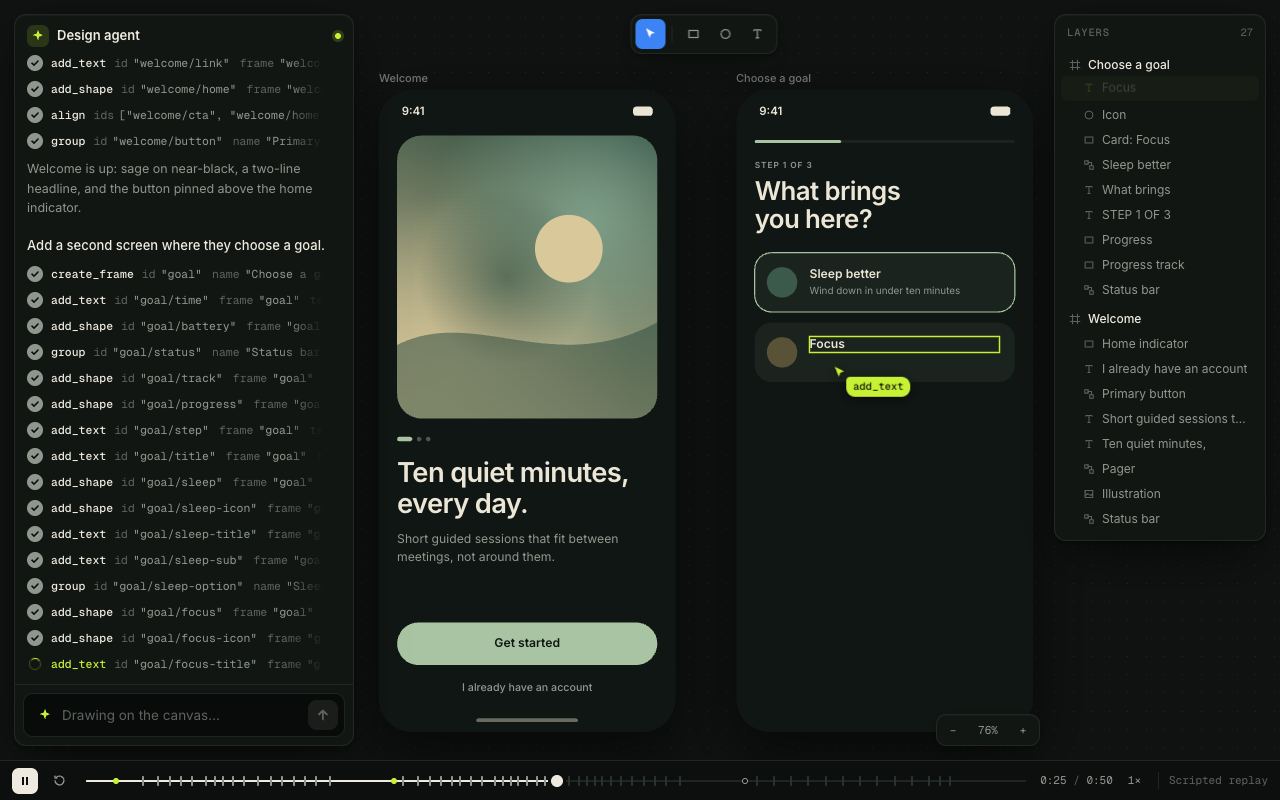
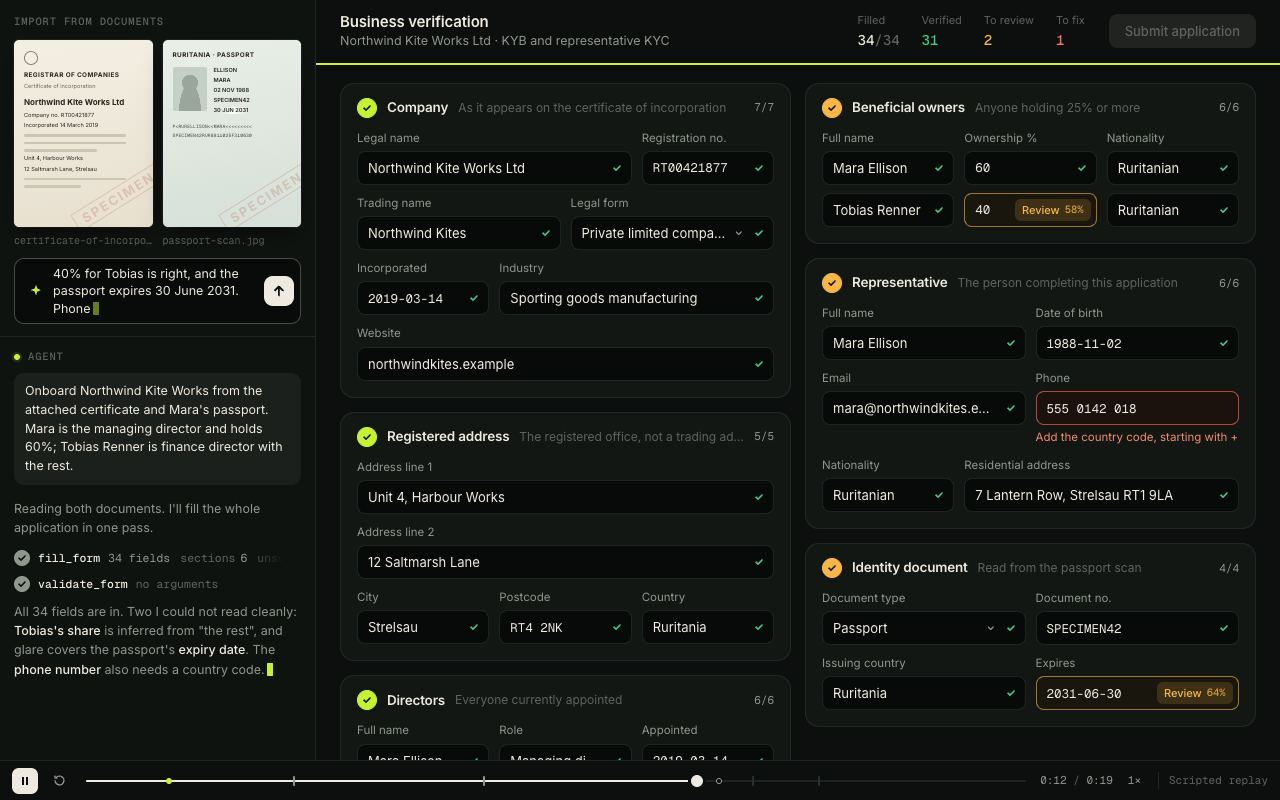
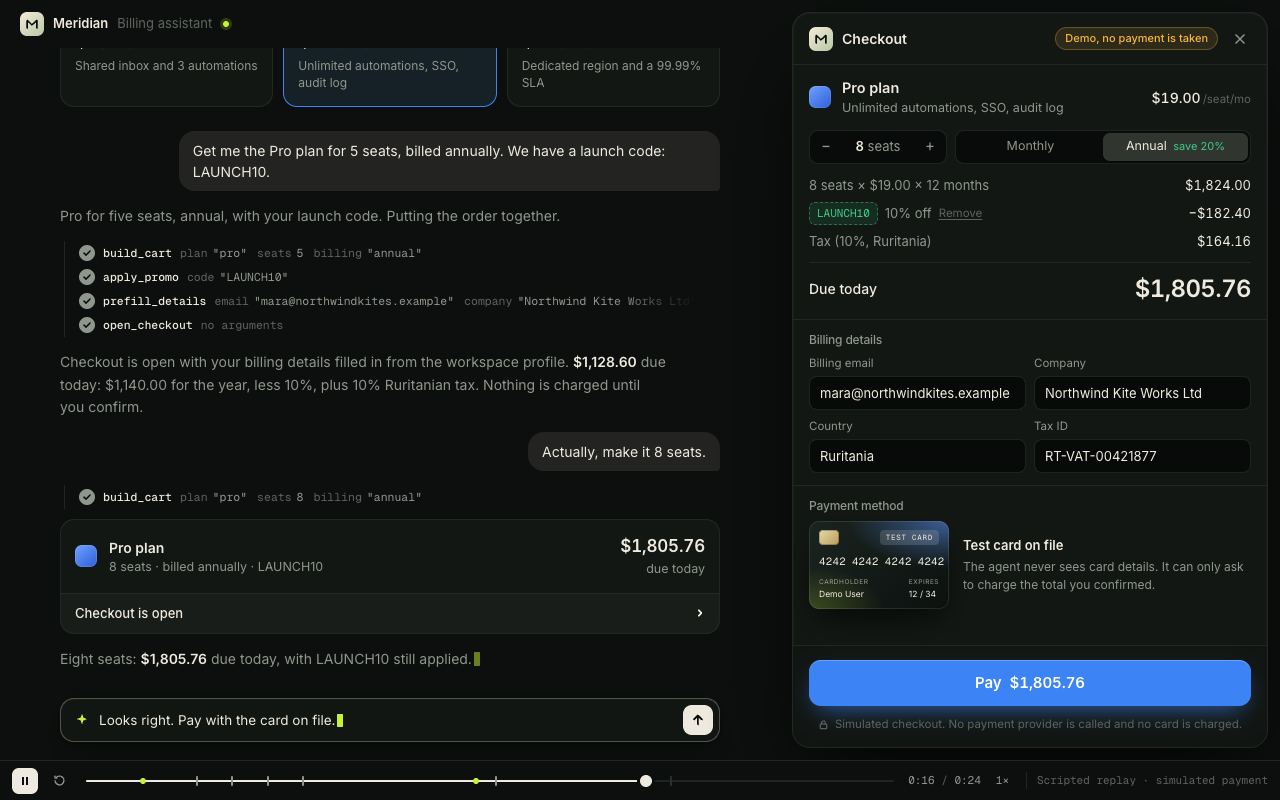
Four products, each operated by an agent through the product’s own functions.
Open the gallery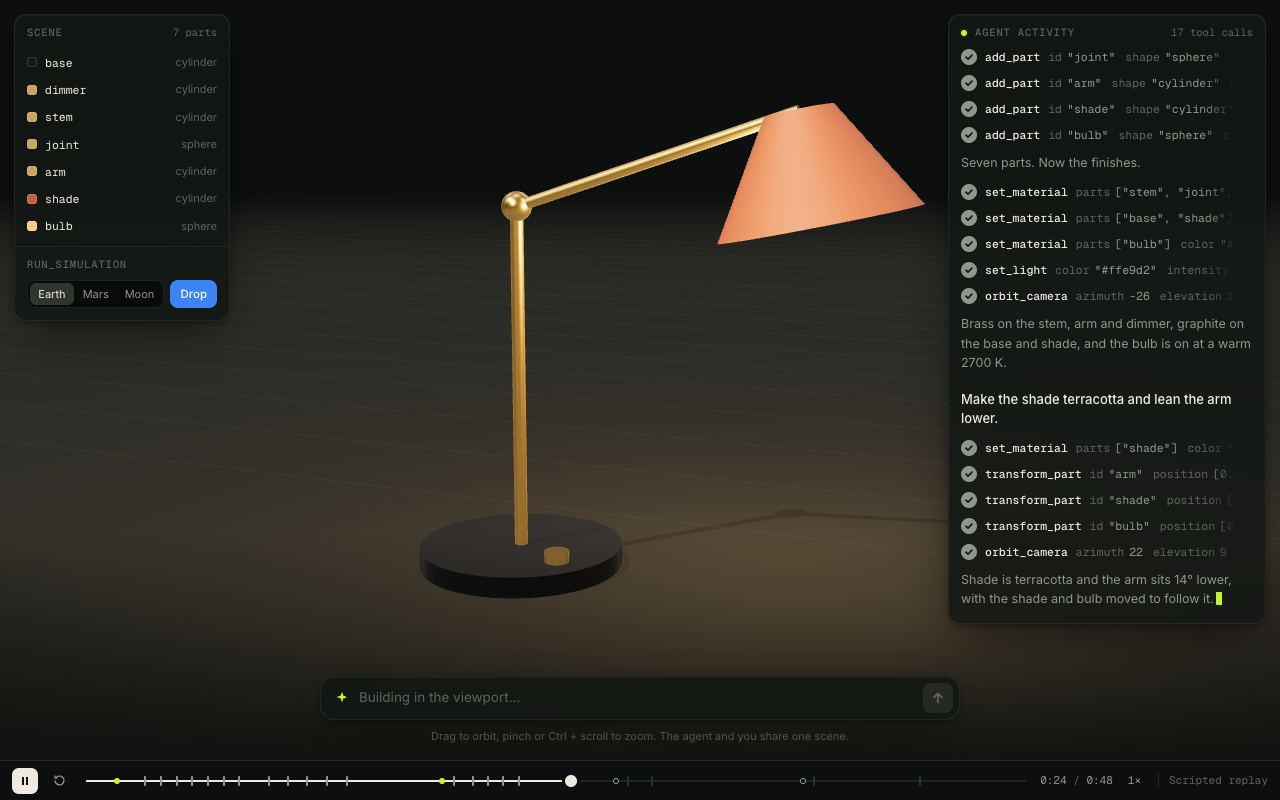
Features
Embed AI experiences in your product.
The parts every team ends up building around an agent, ready on the first day. For agents inside your product and the ones your team runs.
fetch_orderapi_call · 412msfetch_customerapi_call · 380msassessagent_run · returns_agentapprovewait_for_input · waits for yourefundapi_call
Durable runs
Each conversation keeps its thread and memory. A workflow can stop for a person’s approval, wait a day, and pick up at the same step.
thread 7f3a…runningthread 2c91…paused · volume kept
$ ls /workspace
report.csv  notes.md  venv/
Sandboxes on any runtime
Each conversation gets its own Linux machine and a /workspace that outlives pauses. We run OpenSandbox on Kubernetes. Bring E2B, Daytona or your own VMs instead.
cancel_orderruns in your app{ "orderId": "4821" }Tools that run in your app
Give the agent the functions your product already has. They run in the user’s session, and the risky ones ask the user first.
usr_maya$0.065usr_dan$0.050no limitusr_omar$0.010
429 usr_omar’s daily limit is used up. It resets at 00:00 UTC.
Cost and limits per end user
Every model call is priced against the person who made it. Cap an end user, an agent, an API key or a tag, and the next call over the cap never reaches the provider.
# agents/returns_agent.md
[model_settings]
model = "zai/glm-5.2"

# agents/product_finder.md
[model_settings]
model = "gpt-4.1-mini"
Any model, your keys
Start on our key, then add yours for any of 13 providers. Set one default model and override it per agent.
- Telegram
@acme_support_bot - WhatsApp
shared number - Webhook
/workflows/webhook/acme-refund - Schedule
0 0 9 * * MON - MCP
github · linear
Channels and integrations
The same agent answers on Telegram and WhatsApp, runs from a webhook or a cron schedule, and reaches your other tools through MCP.
Architecture
Distri runs the agent. Your product stays yours.
Most agent platforms ask you to move the work to them. Distri sits next to the product you have, and nothing gets rebuilt for the agent.
Distri runs
- The agent loopThreads, memory, skills and multi-step plans, from a markdown file.
- The AI gatewayEvery provider, with traces, attribution and limits on each call.
- Channels and workflowsBots, webhooks and schedules for the same agents.
- SandboxesIsolated code execution, switched on per agent.
- TracesEvery turn, tool call and token, to debug and to bill.
Your product keeps
- Screens and stateClient-side tools call your own functions; the UI updates as it does on a click.
- Auth and permissionsTools run in the user’s session, so the agent can do what the user can do.
- APIs and dataYour backend, and the MCP servers you already expose.
- Provider accountsBring your own LLM keys; the account stays yours.
Where your users are
- auth handshake
- client-side tools
- approve in your UI
- durable runs
- workflows
- sub-agents
- schedules
- A2A
- MCP
- agents
- skills
- templates
- threads
- multi-provider
- cost attribution
- observability
Comparison
Managed-platform speed, without handing over the platform.
Building it yourself takes months. Managed agent platforms get you live fast, then decide your models, your cloud, your data and your bill.
- Platform
- TelegramWhatsAppDiscord
- Bot token
- 7421963:AAF••••••••••••
- Runs
- refund_order workflow
- Trigger
- MessageScheduleWebhook
/start/stop/reset/status/help
Refund order 4821, the lamp arrived broken
Order #4821
Ceramic lamp · $64.00
Paid by card on 12 Nov
Refund the full amount?
refund_order · resumed after wait_for_input
Done. $64.00 is on its way back to the card ending 4242, and the customer has been emailed.
Channels, workflows and bots
The same agent, wherever the work continues.
Not every step happens on your screens. The agent you embedded can answer in a chat thread, run on a schedule, or wait for an approval from your team.
Slack, Telegram, WhatsApp and Discord
The agent answers where your team and your customers already talk. Pick the agent and connect the channel; there is no server to deploy.
Email, CRMs and internal tools, through workflows
A workflow starts on a schedule or a webhook, calls your APIs, and can wait for a person before it goes on.
Anything else, through the API
Every agent answers over a streaming API, so your backend, a cron job or another agent can run it.
Built-in AI gateway
Understand, manage and optimise your LLM traffic.
Every model call your agents make goes through Distri’s gateway: traced end to end, attributed to the agent and the end user, held to your limits, on whichever providers you use.
- Cost
- $212.40
- Tokens
- 18.4M
- Model calls
- 41,280
support_agentv0.4.121,4009.6M$118.20form_fillerv0.2.012,3004.1M$38.90refund_orderworkflow5,1802.9M$34.10weekly_digestv0.1.32,4001.8M$21.20End-to-end observability
Every agent run is a trace: agent, model and tool spans with timings, tokens and cost.
Usage attribution
Every model call is counted against the agent, end user, API key, use case and model.
Limits before the call
Cap tokens or USD per workspace, agent, end user or API key. Over the cap, the call never reaches the model.
Multiple providers, your keys
OpenAI, Anthropic, Gemini, Bedrock, Azure and more, a model per agent. The provider accounts stay yours.
Built on Distri
Start with one agent, in one flow your users already know.
Free to self-host. Distri Cloud has a free tier. See pricing →